Writing
While I Was Building a Wheel at Home, Sports Cars Drove Past: The Story of Taksim
How an idea for cost optimisation evolved into an Intelligence Control Plane for developer tools.
Also available in Turkish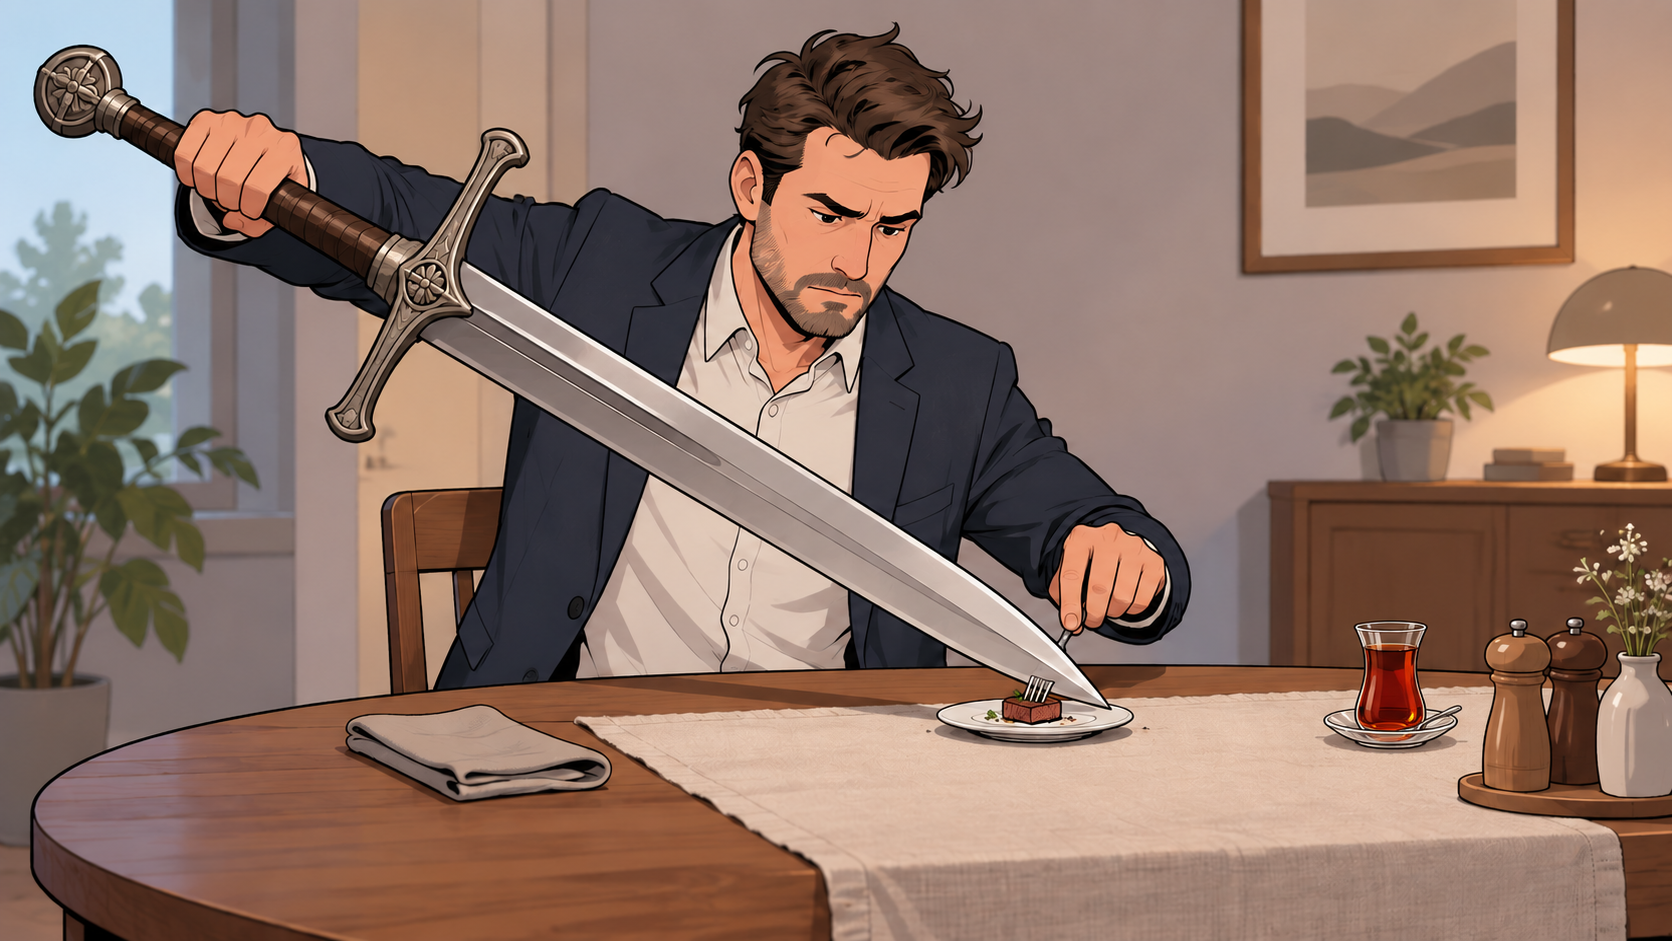
Using a frontier model for every task can feel a little like this.
While I Was Building a Wheel at Home, Sports Cars Drove Past: The Story of Taksim
How an idea for cost optimisation evolved into an Intelligence Control Plane for developer tools — while some of the biggest names in technology began moving towards the same problem.
There is a curious assumption behind much of AI-assisted software development: if we want the best result, we should give every task to the most powerful model available.
At first glance, that sounds reasonable. If we expect an agent to understand a codebase, make sound architectural decisions, run tests and work autonomously for hours, why would we give it a weaker model? New and more capable models arrive almost every week, making the pull towards the latest and strongest option even harder to resist.
The problem is that not every task requires the same level of intelligence.
Renaming a file, applying a known pattern, generating a few similar tests or making a clearly specified small fix is not the same as finding the root cause of an ambiguous production issue. Yet when we work with tools such as Claude Code, Codex, Devin and Copilot, most of us play it safe and keep the powerful model running from beginning to end.
That may preserve quality. But it is not sustainable from a cost perspective. At least not for those of us paying the AI bill out of our own pockets.
Taksim grew directly out of that tension.
I started with local models
My original question was much simpler:
Can I reduce what I spend on cloud models without compromising quality?
I experimented with different local models and Ollama-based workflows on a reasonably powerful Windows machine. On paper, the idea was compelling. A local model could handle repetitive, relatively easy work, while expensive frontier models would step in only for genuinely difficult tasks.
In practice, it was not quite so simple. Some models were too slow for a normal development workflow. Others could complete an apparently easy task, but leave behind a more expensive correction. If a stronger model has to redo work that a smaller model completed cheaply, you have not really saved anything. You have simply spent more time and more tokens.
The experience did not convince me that local models were useless. It taught me something more important: “Local-first” was not a strategy by itself. There needed to be a separate layer responsible for deciding which resource should receive a task, whether the result was good enough and when the work should move to something stronger.
That layer also had to preserve the developer’s existing way of working. Asking people to abandon the tools they like and move to a new chat interface was never going to be realistic. Someone using Claude Code should be able to carry on using Claude Code. Someone using Codex should be able to carry on using Codex.
The first architectural idea looked something like this:
- the tools developers already use;
- one or more private model servers within the team;
- powerful cloud models available when needed;
- an intelligence gateway deciding how work should move between them.
The cloud was not the enemy. It would become an escalation tier: a safe harbour when additional quality or capacity was needed. Competition between cloud providers also keeps producing new price and capacity options. That works in Taksim’s favour. For a system capable of choosing the right resource, it means a broader pool to choose from.
From Agent Workstation to Taksim
The idea first took shape as part of a desktop application called Agent Workstation. It soon became clear, however, that routing decisions did not belong to a chat screen or any single desktop application.
AI usage within a team does not happen in one application. CLI tools, IDE extensions, desktop applications, CI pipelines and autonomous agents may all be active at the same time. The control layer therefore needed to sit beneath these tools, not above them.
That was when the product became Taksim. The name refers not only to the square in Istanbul, but also to the ideas of distributing, dividing and directing something towards the right destination.
My first description of the product was roughly “an AI gateway”. As the project developed, I realised that this was not enough either.
And let’s be honest: this was not an idea that had occurred to nobody else. As I continued working, I came across other products approaching the same problem.
There is something I often remind myself in situations like this: if someone else has already built your idea, do not immediately give up. At worst, you will end up with the code for a working version of a system that solves a real problem, and you will have built up serious knowledge in the process. You may also be approaching the same problem from a different direction.
Seeing similar solutions did not make me abandon Taksim. It made me think more carefully about where its boundaries should be.
Why a model router is not enough
A router can inspect an incoming request and predict which model is the best fit. That is a valuable problem, and there is serious work happening in this area. But in software development, the right choice cannot always be known at the start of a request — especially when so many conversations begin with a simple “hello”. :)
A task may appear easy, then become difficult because of an unexpected dependency in the code. A powerful model can produce a convincing but incorrect solution. A smaller model can perform perfectly when the task is well defined.
So the real question is not only:
Which model should handle this prompt?
We also need to ask: What capabilities does this task require? Did the selected resource actually complete it? What evidence tells us that? If the result is not good enough, when should we escalate and where should the work go next? What can this outcome teach us about the next decision?
That distinction moved Taksim from the idea of a router towards an Intelligence Control Plane for developer AI tools.
Today, the shortest description I use for the project is:
Route by predicted capability, verify by evidence, escalate by necessity.
In other words: predict the capability the task requires, verify the result using real engineering evidence and move to a stronger resource only when necessary.
Taksim’s closed loop
Taksim first tries to understand the task and its context, then selects an appropriate intelligence resource based on the required capabilities and level of risk. The work still runs through the developer’s existing tool. Afterwards, Taksim observes engineering evidence such as tests, builds, linting, source control, CI, tool results and human intervention. This is not intended to be a fixed list; whatever a project uses to control quality should be evidence that Taksim can work with.
If the result is insufficient, the task can be repaired or escalated to a stronger resource. If it is good enough, the verified outcome can inform future choices. The process therefore does not end with “select and send”. Selection, execution, verification, repair or escalation, and learning all become part of the same loop.
The word “resource” is deliberate. The same model running in different environments, at different reasoning levels or with different tool capabilities does not represent the same resource. Taksim needs to keep model, provider, runtime, developer client and execution configuration as separate concepts.
For the same reason, the economic goal is not “the cheapest token”:
Expected cost per successfully completed engineering outcome.
A task that starts cheaply but has to be repeated three times may be less economical than one that appears expensive but succeeds on the first attempt.
The sports cars driving past
When I started Taksim, the only similar approach I knew about was Copilot Auto. As I researched the problem, I discovered Not Diamond, followed by Edgee.ai — a name that naturally caught my attention. Later, I read how Uber was addressing the same cost and quality problem in its internal AI infrastructure. Then, just as I was getting close to Taksim’s MVP, GitHub announced HydraFusion.
None of this discouraged me. Quite the opposite. It showed that the problem I was trying to solve at home did not come only from my own way of working. It was a growing, shared need, from individual developers all the way to technology giants.
Copilot Auto
Copilot Auto was one of the closest ideas I knew about when I began working on Taksim. The platform selecting a model on behalf of the user suggested that model choice could eventually become an ordinary, built-in product feature.
At every iteration, I asked myself the same question: Copilot has Auto today; if Claude introduces something similar tomorrow, does Taksim lose its entire purpose?
The answer had to be no. That is why I did not leave Taksim as a layer that merely selects a model. I put verification, engineering evidence, escalation, company policy, capacity management and learning from outcomes at its centre — concerns that a platform’s own Auto feature cannot replace.
If platform-native Auto features become widespread, Taksim should not become obsolete. It should become the control layer above them, using those choices according to company policy and real engineering outcomes.
Not Diamond
Not Diamond positions itself as an intelligent model router for coding agents. Its core promise is to predict the right model for each input and provide frontier-level quality at lower cost. Its Not Diamond Code approach, announced in August 2026, aims to predict future reward and cost for each step in an agent workflow, while also accounting for cache state and long task sequences.
This is one of the problem areas closest to Taksim. The difference emerges in the control loop. Taksim does not want only to recommend a model before execution. It aims to connect the real execution, the engineering evidence produced afterwards, the escalation decision, team policy and the verified outcome within the same system.
Edgee.ai
It does sound rather like one of my projects, doesn’t it? :) But it is not: Edgee.ai was not built by EdgeeTech.
Edgee.ai describes itself as an Agent Gateway. It intercepts and observes agent requests, routes them, compresses tokens, measures cost and provides security and policy controls. Its approach of gaining control without changing the existing agent workflow overlaps strongly with Taksim.
Edgee’s centre of gravity today is the gateway itself, token economics, budget-aware routing and central visibility. Taksim’s differentiating claim is not simply that a task can be run cheaply. It is that the result can be verified with evidence, and that this evidence can be connected safely to future routing decisions.
What does the same problem look like at scale? The Uber example
This problem is not confined to companies building routing products. Uber’s Software Factory article, published in August 2026, shows that as agent usage grows, cost cannot be controlled simply by choosing a cheaper model. Uber considers model-to-task matching, benchmarks, cost per session, live spending indicators and approval mechanisms together. According to its own figures, with the model held constant, the cost per thousand requests fell by roughly 34% from its peak, while cost per session fell by 52%. Dynamic model routing is one of the next steps the company is working on.
The method matters more to me than the percentages. Uber also evaluates models by their results on real workloads, rather than by their names or overall position in a benchmark. Its uReview system offers a good example: Claude 4 Sonnet generates review comments, while o4-mini-high evaluates those comments. The goal is not simply to find the best model. It is to use different models at the right stages and then verify the result separately.
Uber is not a direct competitor to Taksim. It is important because it shows how the same problem becomes visible inside a large engineering organisation.
HydraFusion and HyDRA
Just as I was approaching Taksim’s MVP, GitHub announced Project HydraFusion. HydraFusion aims to provide automatic semantic routing across local, cloud and compound models, presenting the whole system to the developer as a single selectable model.
The underlying HyDRA research predicts separate capability requirements such as reasoning, code generation, debugging and tool use, then selects the lowest-cost model capable of meeting them. It shows that the assumption of “the strongest model for every task” is also being questioned at Microsoft and GitHub scale.
The similarities between HydraFusion and Taksim are real. Both seek to reduce the model-selection burden on developers, use private or local resources alongside cloud models, and balance quality and cost at task level.
The main distinction I see today is that HydraFusion’s publicly described focus is multi-model orchestration and selection. Taksim’s long-term focus is the lifecycle after selection: a canonical execution record, engineering evidence, safe attribution, verification, repair or escalation, capacity and cost governance, and finally outcome learning.
That is why I ask myself the following question with every new feature:
Is this simply another version of Not Diamond- or HydraFusion-style routing, or does it genuinely contribute to Taksim’s own closed-loop execution control plane?
Privacy and availability are not afterthoughts
If Taksim is going to sit in the middle of developer traffic, it cannot compromise on two things.
The first is privacy. Extracting structural signals from a request should not require storing the raw prompt or source code permanently. The principle I use in the project is:
Being prompt-aware does not require being prompt-owning.
This is one of the clearest areas where I want Taksim to stand apart. Even as a solo developer, I do not want to be forced to send my prompts and code through another company’s gateway. Why should an enterprise have to move all of its engineering content beyond its own trust boundary?
Competitors may offer Zero Data Retention or similar security options. Taksim takes a more fundamental approach: raw engineering content should remain inside the customer’s environment wherever possible. A local Connector can inspect the content temporarily and extract the structural signals required for routing; only privacy-safe metadata should be sent to the remote Intelligence layer. Persistent storage should favour structural data such as time, model and runtime identity, token usage, status and evidence level.
The second is availability. If the control layer fails, it cannot leave the developer unable to use their AI tool.
Inference path is sacred. Observability may degrade; availability must not.
If Taksim’s observability, database or intelligence components fail, the inference flow should continue. Put another way: we can afford to lose data; we cannot afford to stop the developer from working.
Where is the project as of September 2026?
Taksim is no longer just a presentation or an architecture diagram. It has a working .NET control-plane core, a local SQLite data layer, a CLI, a local dashboard and a platform-agnostic adapter architecture for connecting different developer tools.
Historical Claude and Devin sessions can be discovered and imported structurally without storing raw content. Client, runtime, provider, model and configuration identities are kept separate. One of the system’s fundamental assumptions is that the resource actually used and the resource recommended by Taksim are not necessarily the same thing.
For Claude, managed routing no longer produces only a shadow recommendation; it can apply the actual model selection. Sonnet 5 is the default for managed requests, while Opus 5 acts as the escalation tier when verification, repair, risk or policy signals require it. An allowed explicit model choice from the user is preserved. Every routing decision can be linked to its corresponding real inference execution through a precise identity, preventing evidence from being assigned to the wrong resource even when a single user request triggers multiple model calls.
On the Codex side, taksim codex can route OpenAI Responses traffic through the local Connector. Codex’s persistent config.toml, CODEX_HOME, arguments and authentication flow remain untouched. Model, status, token and execution information is observed from the Responses JSON or SSE stream without persistently storing the raw prompt, model response or tool content. The first version does not rewrite Codex’s model selection; the immediate goal is to connect its traffic to the control plane safely and accurately.
Both paths share one principle: if Taksim cannot operate, the native client continues along its normal path. Instead of exposing database errors or long stack traces to the user, the intention is to provide a short notice and keep the work moving.
The architecture now has three distinct areas of responsibility. Taksim is the CLI, launcher and user-experience layer. The Connector on the developer’s machine is responsible for local interception, privacy-safe metadata extraction, local decisions and telemetry. Taksim Intelligence will become the remote decision layer, informed over time by resource knowledge, policy and verified outcomes. The local Connector will always produce a usable decision, while remote Intelligence will be allowed to improve that decision only within a strict latency budget. It will never become a mandatory dependency for inference.
Taksim is not yet the final control plane that learns its own routing policy from historical outcomes. The current system has a working managed policy that applies real model selection. Learned or adaptive routing will follow once enough reliable execution evidence exists.
The immediate goal is simpler than adding more features: a developer should be able to use taksim claude and taksim codex in daily work for a week without Taksim getting in the way; clearly see which model was selected and when escalation occurred; and allow the system to collect canonical evidence that is genuinely useful.
What comes next
The first period of real-world use needs to measure more than token savings:
- Which tasks can be completed safely with smaller or private resources?
- Which signals at the beginning of a task are genuinely predictive?
- Which forms of verification evidence reliably represent success?
- What is the cost of repetition and correction after choosing a model that is too weak?
- When does escalation preserve quality while reducing total cost?
- How little can we interfere with the developer’s existing workflow?
I do not want to make a marketing claim such as “X per cent savings” before that data exists. Taksim’s claim should come from verified engineering outcomes, not a benchmark table.
Final thoughts
When I started Taksim, the problem I was trying to solve was the cost of cloud AI. That remains part of the problem, but I no longer think cost alone is the right target.
The real goal is to let a team use all of the intelligence resources available to it — local models, private infrastructure and frontier cloud models — without sacrificing the quality the work requires.
The developer’s tool should not have to change. The required quality should not fall. The cloud should not disappear; it should remain a powerful tier that steps in when needed. And the system should be able to learn from whether its decisions led to the right outcomes.
The problem Taksim is trying to solve is no longer “which model is cheaper?” It is:
How do we give the right work to the right intelligence resource at the right time — and how do we prove that we got it right?
The sports cars driving past did not make that question irrelevant. Quite the opposite: they showed that the road really does lead somewhere.
More about Taksim
To learn more about Taksim, visit taksim.edgee.tech. If you would like to discuss its technical approach or share your own use case, you can reach me on LinkedIn or by email.
I am developing Taksim within EdgeeTech Ltd.